clarinsi4ai
Pre-training data
← Overview · Part of CLARIN.SI resources for AI development · Data as of 22 October 2026
The repository holds about 53B words of pre-training text once known overlaps are removed (114B words across all records), and 50B of it is openly licensed. Per language, Slovenian has the most, roughly 9B words. Web corpora supply most of it: CLASSLA-web 2.0 alone has 17B words in the seven South Slavic languages, and MaCoCu adds seven more languages. For Slovenian, domain corpora add 2.6B words of scientific text, 772M words of legal text and 239M words of parliamentary debate.
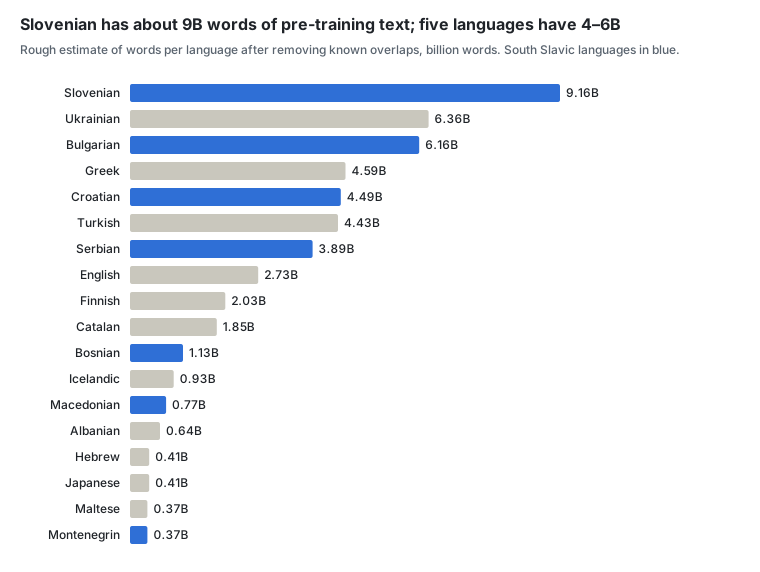
Estimate over all pre-training records after removing known overlaps (see the method). CLASSLA-web 2.0 split by its stated per-language sizes, TURK, Kranjska and yu1Parl by their stated shares, other multilingual records evenly across their languages.
Sections: Web corpora · Reference, news and monitor corpora · Books and literature · Specialised domains: science, law, medicine, education · Parliamentary debates · Social media and user comments · Historical text · Parallel and translation data
Web corpora
CLASSLA-web 2.0 (crawled in 2024) is the current reference for the South Slavic languages. All MaCoCu and CLASSLA-web corpora are CC0; CLASSLA-web and MaCoCu-Genre carry genre labels, and CLASSLA-web 2.0 adds topic labels. Older crawls (the WaC corpora, CLASSLA-web 1.0, BERTić-data) overlap with it in part. The monolingual MaCoCu corpora for the South Slavic languages are left out, as CLASSLA-web 1.0 is a cleaned version of them; the English-paired MaCoCu corpora are independent and listed under parallel data.
Slovenian, including the Slovenian part of multilingual resources
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| South Slavic web corpus collection CLASSLA-web 2.0 · Slovenian part | sl | 2.3B words | CC0 | 2026 |
| Genre-enriched web corpora MaCoCu-Genre · Slovenian part | sl | ≈ 1.8B words | CC0 | 2024 |
| Slovenian web corpus CLASSLA-web.sl 1.0 | sl | 1.8B words | CC0 | 2024 |
| Comparable corpora of South-Slavic Wikipedias CLASSLA-Wikipedia 1.0 · Slovenian part | sl | not stated | CC BY | 2021 |
Sizes marked ≈ are estimates: MaCoCu-Genre from CLASSLA-web.sl 1.0 (1.77B words), on which its Slovenian part is based.
Other languages, and multilingual resources in full
Reference, news and monitor corpora
The largest curated Slovenian collections (metaFida, Gigafida, Trendi) are records without files: they can be queried in the CLARIN.SI concordancers but not downloaded. The downloadable subsets and the Croatian news corpora are non-commercial.
Slovenian, including multilingual resources with Slovenian
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Corpus of combined Slovenian corpora metaFida 1.0 | sl | 4.7B words | none, no files | 2023 |
| Corpus of written standard Slovene Gigafida 2.2 | sl | 1.1B words | none, no files | 2025 |
| Monitor corpus of Slovene Trendi 2026-09 | sl | 1.1B words | none, no files | 2026 |
| Written corpus ccGigafida 1.0 | sl | 103.2M words | CC BY-NC-SA | 2013 |
| Written corpus ccKres 1.0 | sl | 9.8M words | CC BY-NC-SA | 2013 |
| Annotated corpus of Slovenian language-related news articles MetaLangNEWS-Sl | sl | 588.9k words | CC BY-NC-SA | 2020 |
Other languages
Books and literature
The 2026 e-book release adds 231 EPUB samples (the opening part of each book) from 6 Slovenian publishers under CC BY-SA. It is the only sizeable block of contemporary edited long-form prose and poetry in the repository.
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| E-book samples from Slovenian publishers (231 records, EPUB; search the repository for “Sample from the e-book”) | sl | 13.5k pages | CC BY-SA | 2026 |
| Corpus of 1968 Slovenian literature Maj68 3.0 | sl | 1M words | CC BY-NC-SA | 2024 |
| Corpus of daily jokes from the 24ur.com portal Šale24 1.0 | sl | 129.1k words | CC BY-NC | 2024 |
| Collection of Slovenian riddles Uganke 1.0 | sl | 2.8k items | CC BY | 2025 |
| The e-book “Soneti” (Sonnets) | sl | 104 pages | CC BY-SA | 2026 |
| Collection of Slovenian paremiological units Pregovori 1.1 | sl | – | CC BY | 2023 |
Specialised domains: science, law, medicine, education
OSS (2.6B words, CC BY-SA) and COLESLAW (772M words, CC BY) are the two large openly licensed Slovenian domain corpora. KAS 2.0 (1.5B words of academic theses) is restricted to academic users.
Slovenian, including the Slovenian part of multilingual resources
Sizes marked ≈ are estimates: KAS-Abs as the Slovenian share of the abstract files (71,567 of 125,202); TURK as the 94% of the corpus that the record gives as Slovenian.
Other languages, and multilingual resources in full
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Croatian corpus of non-professional written language by typical speakers and speakers with language disorders RAPUT 1.0 | hr | 426.2k words | CC BY-SA | 2021 |
| Monolingual Mining Corpus - RudKorP (ELEXIS) | sr | 136 articles | none, no files | 2020 |
| Corpus of Legislation texts of Republic of Serbia 1.0 | sr | 5 files | CC BY | 2022 |
| Tourism Corpus TURK 3.0 | sl, it, en, de | 29.5M words | CC BY | 2025 |
| Abstracts from the KAS corpus KAS-Abs 2.0 | sl, en | 28.4M words | ACA (BY-NC) | 2022 |
| Corpus of Romanian Academic Genres ROGER | ro, en | 3.3M words | none, no files | 2022 |
Parliamentary debates
ParlaMint covers 29 parliaments with 1.2B words of speaker-attributed transcripts under CC BY. ParlaMint-en.ana is a machine translation of all of them into English (1.4B words).
Slovenian, including the Slovenian part of multilingual resources
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Slovenian parliamentary corpus (1990-2022) siParl 4.0 | sl | 239.2M words | CC BY | 2024 |
| Slovenian parliamentary corpus (1990-1992) SlovParl 2.0 | sl | 10.8M words | CC BY | 2017 |
| Carniolan Provincial Assembly corpus Kranjska 1.0 · Slovenian part | sl | ≈ 6.3M words | CC BY | 2023 |
| Parliamentary corpus of first Yugoslavia (1919-1939) yu1Parl 1.0 · Slovenian part | sl | ≈ 0.4M words | CC BY | 2023 |
| Corpus of political party programs Programi2022 | sl | 330.6k words | CC BY-NC-SA | 2022 |
| Multilingual comparable corpora of parliamentary debates ParlaMint 5.0 · Slovenian part | sl | not stated | CC BY | 2025 |
| Linguistically annotated multilingual comparable corpora of parliamentary debates ParlaMint.ana 5.0 · Slovenian part | sl | not stated | CC BY | 2025 |
Sizes marked ≈ are estimates: Kranjska and yu1Parl from the share of Slovenian sentences given in the record (58% and 3%).
Other languages, and multilingual resources in full
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Multilingual comparable corpora of parliamentary debates ParlaMint 5.0 | 29 languages | 1.2B words | CC BY | 2025 |
| Linguistically annotated multilingual comparable corpora of parliamentary debates ParlaMint.ana 5.0 | 29 languages | 1.2B words | CC BY | 2025 |
| Parliamentary corpus of first Yugoslavia (1919-1939) yu1Parl 1.0 | sr, hr, sl | 13.3M words | CC BY | 2023 |
| Carniolan Provincial Assembly corpus Kranjska 1.0 | sl, de | 10.9M words | CC BY | 2023 |
| Comparable corpus of parliamentary debates ParlaMint-IL 1.0 | heb | 409.4M words | CC BY-SA | 2025 |
| Ukrainian parliamentary corpus ParlaMint-UA 4.0.1 | uk, ru | 42M words | CC BY | 2023 |
| Comparable corpus of parliamentary debates ParlaMint-ES-CN 1.0 | es | 39.8M words | CC BY | 2025 |
| Linguistically annotated multilingual comparable corpora of parliamentary debates in English ParlaMint-en.ana 5.0 | en | 1.4B words | CC BY | 2025 |
Social media and user comments
The Janes corpora (2017) remain the main source of Slovenian non-standard written language. The large news-comment collections for Croatian, Estonian and Latvian are no-derivatives licensed, which rules out most training uses.
Slovenian, including the Slovenian part of multilingual resources
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Dataset and baseline model of moderated content FRENK-MMC-RTV 1.0 | sl | 325.2M words | CC BY-SA | 2018 |
| Twitter corpus Janes-Tweet 1.0 | sl | 139.3M words | CC BY-NC | 2017 |
| Forum corpus Janes-Forum 1.0 | sl | 47.1M words | CC BY | 2017 |
| Blog post and comment corpus Janes-Blog 1.0 | sl | 34.5M words | CC BY | 2017 |
| News comment corpus Janes-News 1.0 | sl | 14.8M words | CC BY | 2017 |
| Slovenian Twitter dataset 2018-2020 1.0 | sl | 13M texts | CC BY-SA | 2021 |
| Wikipedia talk corpus Janes-Wiki 1.0 | sl | 5M words | CC BY-SA | 2017 |
| Annotated corpus of Slovenian language-related news comments MetaLangNEWS-COMMENTS-Sl | sl | 44.2k words | CC BY-NC-SA | 2020 |
| Facebook metadata dataset LiLaH-HAG · Slovenian part | sl | not stated | CC BY-NC-SA | 2022 |
Other languages, and multilingual resources in full
Historical text
sPeriodika (708M words of Slovenian periodicals, 1771–1914, CC BY-SA) is the largest historical source. It contains OCR noise; a matching post-OCR correction set is listed under post-training.
Slovenian, including the Slovenian part of multilingual resources
Other languages, and multilingual resources in full
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Annotated Corpus of Pre-Standardized Balkan Slavic Literature 1.1 | bg, mk | 53.3k words | CC BY-SA | 2021 |
| Slovenian manuscript sermons by Ignacij Holzapfel 1.0 | sl, de, la | 220 pages | CC BY-SA | 2024 |
| Epigraphic corpus of Medieval and Early Modern inscriptions in Slovenia MEMIS 1.0 | sl, la | 51 texts | CC BY-SA | 2020 |
| Disasters corpus in classical Arabic sources DiCCAS | ar | 289.5k words | CC BY-NC-SA | 2026 |
Parallel and translation data
MaCoCu provides CC0 English-paired corpora for 14 languages, from 10.6M (Icelandic) to 239M words (Ukrainian). DGT-UD adds 2.1B words of EU translation memories in 23 languages.
Slovenian, including the Slovenian part of multilingual resources
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Parallel corpus EN-SL RSDO4 2.0 · Slovenian part | sl | 3.1M sentences | CC BY-SA | 2021 |
| Slovene-English parallel corpus MaCoCu-sl-en 2.0 · Slovenian part | sl | 1.9M segments, ≈ 42M words | CC0 | 2023 |
| Slovene-English parallel corpus slenWaC 1.0 · Slovenian part | sl | ≈ 14M words | CLARIN.SI web-corpus licence | 2016 |
| Machine Translation datasets from the KAS corpus KAS-MT 1.0 · Slovenian part | sl | 496k sentences, ≈ 11M words | ACA (BY-NC) | 2022 |
| MULTEXT-East “1984” document corpus 4.0 · Slovenian part | sl | ≈ 6.7k sentences | CC BY-NC-SA | 2010 |
| Parallel corpus of idiomatic text ParaDiom 1.0 · Slovenian part | sl | 2,000 sentences, ≈ 33k words | CC BY-NC-SA | 2022 |
| Parallel sense-annotated corpus ELEXIS-WSD 2.0 · Slovenian part | sl | 2,024 sentences | CC BY-SA | 2026 |
| JRC EU DGT Translation Memory Parsebank DGT-UD 1.0 · Slovenian part | sl | not stated | CC BY | 2018 |
| Slovenian translation corpus Spook 1.1 · Slovenian part | sl | not stated | ACA (BY-NC) | 2026 |
Sizes marked ≈ are estimates: the “1984” corpus as one of its ten language versions; bilingual corpora as half of the word count of the pairs.
Other languages, and multilingual resources in full
Other stages: Pre-training data · Speech and multimodal data · Post-training data · Evaluation and benchmarks · Lexical and knowledge resources · Models and tools