clarinsi4ai
Speech and multimodal data
← Overview · Part of CLARIN.SI resources for AI development · Data as of 22 October 2026
The repository holds about 12,200 hours of recorded speech. ParlaSpeech 4.0 gives 10,313 hours of aligned parliamentary speech: Slovenian 4,080 h, Croatian 3,110 h, Czech 1,218 h, Polish 1,009 h and Serbian 896 h. Beyond parliament, Slovenian adds ARTUR (1,067 h, built for ASR), Gos 2.1 (319 h, academic users only), 304 h of audiobook samples and the 100-hour Gail Valley dialect corpus, for about 5,900 hours in total. Multimodal data is limited to two recent Slovenian sets.
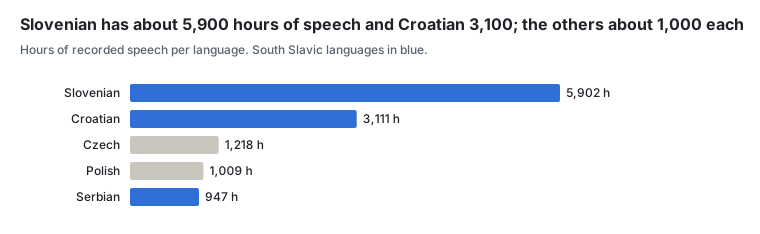
Each record’s stated duration counted once; transcript-only releases and resources derived from other recordings left out.
Sections: Speech recordings · Spoken-language transcripts · Multimodal data
Speech recordings
ParlaSpeech 4.0 is listed once per language. Each language comes as sentence-aligned transcripts with filled and silent pauses (and word stress for Croatian and Serbian), with the FLAC audio in a separate record.
Slovenian, including multilingual resources with Slovenian
Other languages
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| ParlaSpeech 4.0 · Croatian: transcriptions, audio | hr | 3,110 h | CC BY-SA | 2026 |
| ParlaSpeech 4.0 · Czech: transcriptions, audio | cs | 1,218 h | CC BY-SA | 2026 |
| ParlaSpeech 4.0 · Polish: transcriptions, audio | pl | 1,009 h | CC BY-SA | 2026 |
| ParlaSpeech 4.0 · Serbian: transcriptions, audio | sr | 896 h | CC BY-SA | 2026 |
| ASR training dataset for Serbian JuzneVesti-SR v1.0 | sr | 51 h | CC BY-SA | 2022 |
| The “Mići Princ” text and speech dataset of Chakavian micro-dialects | hr, ckm | 11.6k words | CC BY-SA | 2024 |
| Business English learner speech corpus SAPS | en | 55.4k words | CC BY-NC | 2021 |
Spoken-language transcripts
These corpora have no audio in the repository, or only small amounts; their main value is as spoken-language text.
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| ASR database ARTUR 1.0 (transcriptions) | sl | 884 h | CC BY-SA | 2023 |
| Spoken corpus Gos 2.1 (transcriptions) | sl | 2.5M words | CC BY-SA | 2023 |
| Dialogue act annotated spoken corpus GORDAN 1.0 (transcription) | sl | 1 h | CC BY | 2020 |
| The “Mobile languages” corpus MoJezik 1.0 (transcription) | sl | 78.9k words | CC BY | 2025 |
| Corpus of metaphorical expressions in spoken Slovene language G-KOMET 1.0 | sl | 52.5k words | CC BY-NC-SA | 2022 |
| SNABI database for continuous speech recognition 1.2 | sl | 15k items | CC BY-NC-SA | 2002 |
| Spoken Torlak dialect corpus 1.0 (transcription) | sr | 498k words | CC BY-NC | 2020 |
| Corpus of Serbian Forms of Address 1.1 | sr | 171.5k words | CC BY-NC-SA | 2023 |
| Map task corpus of heritage BCMS 1.0 | sr, hr, bs, hbs | 13k words | CC BY-NC-SA | 2023 |
| Heritage Bosnian, Croatian, and Serbian spoken by Second Generation Speakers in Germany He-BCS-Ge | bs, hr, sr | 15 texts | CC BY-NC | 2024 |
| Albanian Spoken Corpus in Kosovo 1.0 | sq, aln | 160.2k words | CC BY | 2024 |
Multimodal data
The vision-language instruction set SLO-VLM-IT (1.1M items) is listed under post-training.
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Multimodal document understanding dataset from “Ilustrirani Slovenec” | sl | 39.8k texts | CC BY-NC | 2026 |
Other stages: Pre-training data · Speech and multimodal data · Post-training data · Evaluation and benchmarks · Lexical and knowledge resources · Models and tools