clarinsi4ai
Post-training data
← Overview · Part of CLARIN.SI resources for AI development · Data as of 22 October 2026
All instruction data in the repository is Slovenian: the GaMS-Instruct family and SloLexQA hold about 2.2M prompt–response pairs, 2.17M of them from three 2026 medical and pharmaceutical sets built from databases with LLM enrichment. Fully human-written data is limited to GaMS-Instruct-DH (10k pairs, digital humanities); the general-domain GaMS-Instruct-GEN has 6.8k GPT-4-generated pairs, manually validated. The only conversational data is the machine-generated vision-language set SLO-VLM-IT, and there is no preference data. The 68 task-specific supervised sets cover more languages and can be converted into instruction format.
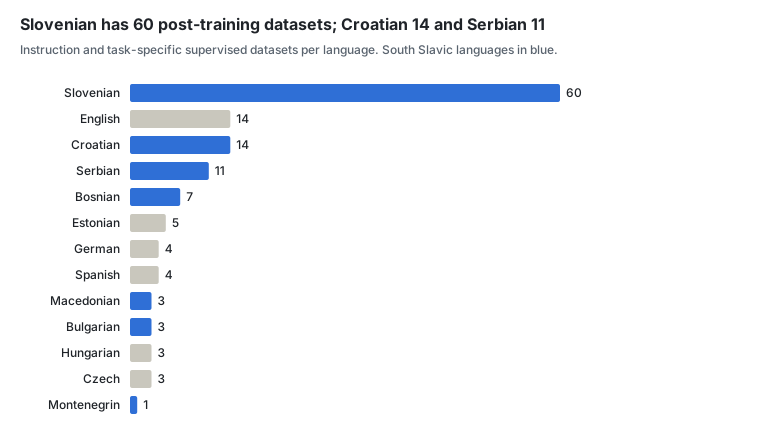
Datasets with files; a multilingual dataset counts once for each of its languages.
Sections: Instruction, QA and alignment data · Text-to-text: correction, normalisation, simplification, summarisation · Linguistic annotation: tagging, parsing, NER, coreference, multiword units · Semantics, knowledge and information extraction · Text classification: sentiment, hate speech, genre, topic, stance, language ID
Instruction, QA and alignment data
Three expert Q&A archives (ŠUSS, TermSvet, Terminologišče) contain real questions answered by linguists and terminologists. They are not yet in instruction format but are natural candidates for supervised fine-tuning.
Text-to-text: correction, normalisation, simplification, summarisation
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Summarization datasets from the KAS corpus KAS-Sum 1.0 | sl, en | 1.1B words | ACA (BY-NC) | 2022 |
| Developmental corpus Šolar 3.0 | sl | 1.6M words | CC BY-NC-SA | 2022 |
| Dataset of normalised Slovene text KonvNormSl 1.0 | sl | 427k words | CC BY-SA | 2016 |
| CMC training corpus Janes-Norm 3.0 | sl | 283.3k words | CC BY-SA | 2022 |
| Corpus of comma placement Vejica 1.3 | sl | 104.2k sentences | CC BY-NC-SA | 2018 |
| Post-edited and error annotated machine translation corpus PErr 1.0 | 5 languages | 43.9k words | CC BY-SA | 2016 |
| CMC shortening corpus Janes-Kratko 1.0 | sl | 20.2k words | CC BY-SA | 2017 |
| Tweet comma corpus Janes-Vejica 1.0 | sl | 14k words | CC BY-SA | 2017 |
| Slovene text simplification dataset SloTS | sl | 973 entries | CC BY | 2022 |
| Post-OCR correction training dataset sPeriodika-postOCR | sl | 409 texts | CC BY-SA | 2024 |
Linguistic annotation: tagging, parsing, NER, coreference, multiword units
Slovenian, including multilingual resources with Slovenian
Other languages
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Croatian linguistic training corpus hr500k 2.0 | hr | 499.6k words | CC BY-SA | 2023 |
| Serbian linguistic training corpus SETimes.SR 2.0 | sr | 97.7k words | CC BY-SA | 2023 |
| Serbian Twitter training corpus ReLDI-NormTagNER-sr 3.0 | sr | 92.3k words | CC BY-SA | 2023 |
| Croatian Twitter training corpus ReLDI-NormTagNER-hr 3.0 | hr | 89.9k words | CC BY-SA | 2023 |
| Macedonian linguistic training corpus SETimes.MK 0.1 | mk | 13.3k words | CC BY-SA | 2023 |
Semantics, knowledge and information extraction
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Word-sense disambiguation corpus SloDicWSD 1.0 | sl | 2M words | CC BY | 2025 |
| Slovene Translation of the Atomic 2020 data set SloATOMIC 2020 | sl | 1.3M entries | CC BY-SA | 2022 |
| Slovene corpus for general relation extraction SloREL 1.1 | sl | 245.3k sentences | CC BY | 2022 |
| Slovenian Definition Extraction training dataset DF_NDF_wiki_slo 1.0 | sl | 38.6k sentences | CC BY-SA | 2023 |
| Slovenian keyword extraction dataset from SentiNews 1.0 | sl | 7.5k articles | CC BY-SA | 2022 |
| Slovenian social assistance rights text data collection SSAR 1.0 | sl | 6.9k sentences | CC BY-SA | 2024 |
| Corpus for identifying sex education concepts SemSex 1.0 | sl | – | CC BY | 2023 |
| Semantic hypergraph corpus SemCRO 1.0 | hr | 184 sentences | CC BY-SA | 2020 |
| Keyword extraction datasets for Croatian, Estonian, Latvian and Russian 1.0 | hr, et, lv, ru | – | CC BY-NC-ND | 2021 |
| Natural Language 2 Semantic Hypergraph Dataset NL2SH 1.0 | en | 6k words | ACA (BY-NC) | 2023 |
Text classification: sentiment, hate speech, genre, topic, stance, language ID
Slovenian, including multilingual resources with Slovenian
Other languages
Other stages: Pre-training data · Speech and multimodal data · Post-training data · Evaluation and benchmarks · Lexical and knowledge resources · Models and tools