clarinsi4ai
Models and tools
← Overview · Part of CLARIN.SI resources for AI development · Data as of 22 October 2026
The repository holds encoder models, task models and speech and translation systems, but no generative LLM weights; the GaMS models referenced by the instruction sets are distributed on Hugging Face. These resources are most useful as baselines, as annotators for building training data (CLASSLA-Stanza, SPOT-Trankit), and for evaluation (SloBENCH, ASR model evaluator).
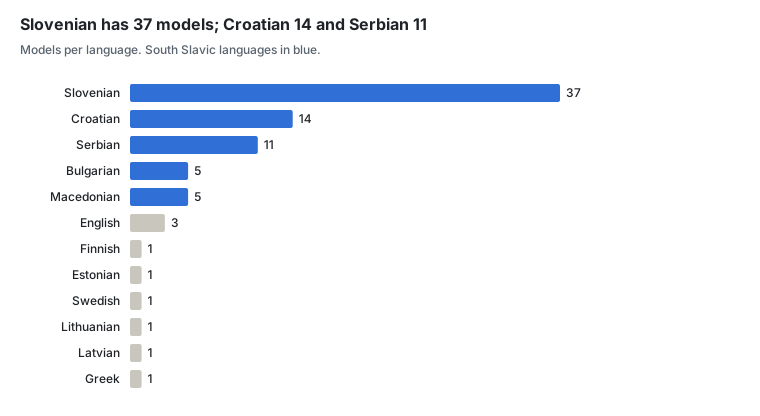
A multilingual model counts once for each of its languages; RSDO web-service records excluded.
Models
The RSDO speech recognition, translation and punctuation models also have matching NeMo web-service records (3 records, Apache 2.0), listed in the spreadsheet.
Slovenian, including multilingual resources with Slovenian
Other languages
| Resource | Languages | Size | Licence | Year |
|---|---|---|---|---|
| Word embeddings CLARIN.SI-embed.hr 2.0 | hr | 3.4M entries | CC BY-SA | 2023 |
| Word embeddings CLARIN.SI-embed.bg 1.0 | bg | 2.7M entries | CC BY-SA | 2023 |
| Word embeddings CLARIN.SI-embed.sr 2.0 | sr | 2.7M entries | CC BY-SA | 2023 |
| Word embeddings CLARIN.SI-embed.mk 2.0 | mk | – | CC BY-SA | 2023 |
Tools
| Resource | Languages | Licence | Year |
|---|---|---|---|
| ASR model evaluator | sl | Apache 2.0 | 2022 |
| Service for querying dependency treebanks Drevesnik 1.2 | sl | Apache 2.0 | 2025 |
| Corpus extraction tool LIST 1.3 | sl, en | Apache 2.0 | 2024 |
| CORDEX inflectional lookup data 1.0 | sl | CC BY-NC-SA | 2023 |
| R crawlers for five Slovenian web media 1.0 | sl | CC BY-SA | 2017 |
| ZRCola 2 | sl, en, ru | GPL-3.0 | 2016 |
| SloBENCH evaluation framework | – | Apache 2.0 | 2021 |
| Q-CAT Corpus Annotation Tool 1.5 | – | Apache 2.0 | 2023 |
| Dependency tree extraction tool STARK 3.1 | – | Apache 2.0 | 2024 |
| The Orange workflow for observing collocation trends ColTrend 1.0 | – | Apache 2.0 | 2020 |
| The Orange workflow for observing collocation clusters ColEmbed 1.0 | – | Apache 2.0 | 2020 |
| Font ZRCalo 1.0 | – | CC BY | 2023 |
| DigiLing e-Learning Hub: e-Courses for Digital Linguistics | en | CC BY | 2019 |
| UPSKILLS Teaching and Learning Content | en | CC BY | 2023 |
Other stages: Pre-training data · Speech and multimodal data · Post-training data · Evaluation and benchmarks · Lexical and knowledge resources · Models and tools